Your data, working. Not just sitting in warehouses.
We build the pipelines, warehouses, and analytics infrastructure that turn raw data into reliable business intelligence, fast, clean, and maintainable.
Free, no commitment. Takes about 30 seconds.
* For common roles like full-stack. Other roles typically take 7 to 10 days.
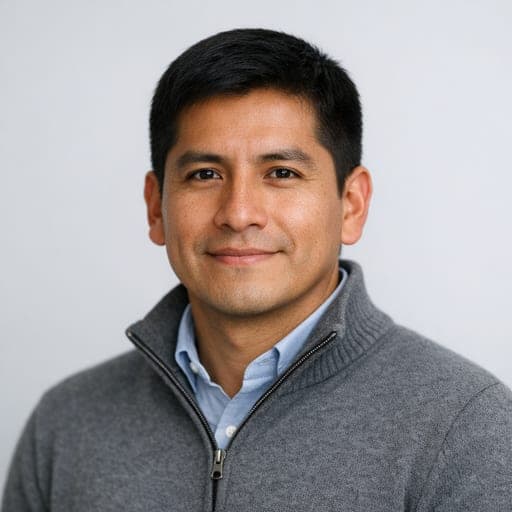
Your next engineer
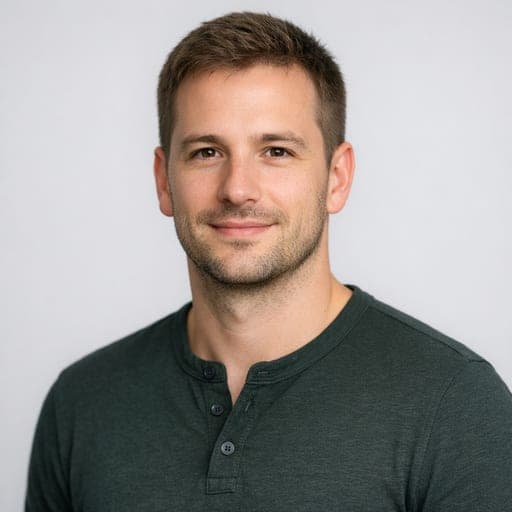
Lucas A.
Senior Full-Stack Engineer
 São Paulo, BR·9 yrs
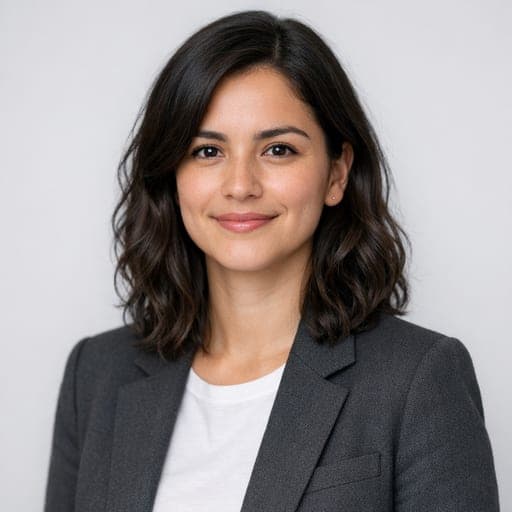
Sample profiles from our talent network: 3,000+ professionals in 6 countries.
200+ people placed with teams like


200+
People Allocated
5%
Of applicants make our active bench
97%
Client Satisfaction
3 days*
Average Time to First Match
Across fintech, edtech, SaaS, and e-commerce engineering teams in the US
* For common roles like full-stack. Other roles typically take 7 to 10 days.
What it is
Data infrastructure you can actually trust.
Most companies have data sitting in five different systems with no reliable way to combine it. Dashboards break when someone renames a column.
Analysts spend more time cleaning data than analyzing it. We build the infrastructure that fixes this: ingestion pipelines, transformation layers, a warehouse your whole team can query, and monitoring that tells you when something breaks before your CEO notices.
Why it works
Infrastructure that your analysts and engineers both trust.
Clean, unified data warehouse
One source of truth across all your systems, CRM, product analytics, payments, support, structured so any analyst can query it without a data engineer on call.
Reliable ingestion pipelines
Automated pipelines that move data from source systems to your warehouse on schedule, with error handling, alerting, and automatic recovery.
Transformation with dbt
Your raw data cleaned, joined, and modeled using dbt so your business metrics are defined once, tested, and consistent across all dashboards.
Data quality monitoring
Automated tests that catch broken pipelines, schema changes, and anomalous values before they corrupt reports or trigger wrong decisions.
Analytics-ready tables
Pre-aggregated, denormalized tables built for fast BI tool queries.
Scalable architecture
Systems designed to handle 10x your current data volume without rewriting.
Want to see profiles before you decide?
Tell us who you need. The first shortlist arrives in 3 days for common roles, with no commitment.
The process
Audit, design, build, monitor.
- 01
Data audit
We map your current data sources, identify quality issues, and understand how your team actually uses data today.
- 02
Architecture design
We propose a warehouse and pipeline architecture based on your data volume, team size, and BI tool requirements.
- 03
Ingestion and warehouse build
We build connectors for each data source, set up your warehouse (BigQuery, Snowflake, or Redshift), and get all data flowing reliably.
- 04
Transformation and modeling
We write dbt models that define your business metrics: revenue, activation, churn, LTV.
- 05
Monitoring and handoff
Automated pipeline monitoring, alerting, and documentation.
What you are actually signing
Try an engineer for two weeks. Keep them only if they earn it.
Shortlist in 3 days*
Three candidates reviewed against your brief by hand, not a database dump.
2-week trial
If the fit is wrong, you pay for the days worked and nothing else.
30-day replacement
Engineer leaves or does not work out in the first 30 days?
Month-to-month
30 days notice.
Not ready for a call? Just tell us who you need.
No calendar, no sales sequence. Send this and we will reply with profiles that fit.
How we use AI
AI in every step.People sign off on all of it.
Every team we place works with AI tools from day one and keeps training on them as new models and practices appear. It makes the work faster. It does not replace the review.
What stays human
- Peer review on every pull request
- Manual and automated testing
- QA before anything ships
- Architecture and product decisions
Planning
Break down scope, estimate, and spot risks before the sprint starts.
Coding
Scaffold, refactor, and pair with AI inside the editor.
Testing
Generate test cases and edge cases. People decide what passes.
Documentation
Keep docs and PR descriptions current without the Friday scramble.
Research
Compare libraries, read specs, and prototype faster.
Code review
First pass by AI, final call by a person.
Need AI inside your product? The engineers we place build that too.
AI & ML developmentBest fit
For teams drowning in data they can't use.
Startups scaling beyond spreadsheets
Your data is in five tools and nobody agrees on the numbers.
Analytics teams with broken pipelines
Your analysts waste hours every week fixing broken reports.
Companies with acquisition-created data silos
You acquired a company and now have two systems of record for customers.
Engineering teams building data products
Product teams that want to build data-driven features, recommendations, personalization, risk scoring, and need reliable data infrastructure underneath.
Our stack
The modern data stack, in full.
Before you decide
The doubts everyone has before hiring us.
And what we do about each one.
I've been burned by agencies that just forward resumes.
Only 5% of applicants pass our five-dimension vetting.
Remote engineers disappear or jump to another job.
Your account contact runs a structured check-in every month with you and, separately, with the engineer, so problems surface early.
It will cost more than hiring directly or using a freelancer.
You pay one monthly invoice with no placement fee.
No placement feeI don't want outsiders touching our code and data.
Every engineer signs a full NDA before day one, code belongs to your company from the moment it is written, and access goes only to the people who need it, under your security policies.
FAQ
Questions about data engineering
Fix your data infrastructure
Start with the audit.
A 1-week data audit gives you a clear picture of what's broken and a prioritized plan to fix it. Most clients start building within 2 weeks.
What happens next
- 1
You tell us what you need. It takes about 2 minutes.
- 2
A real person replies within 4 business hours.
- 3
First shortlist in 3 days*. You interview and choose.
* For common roles like full-stack. Other roles typically take 7 to 10 days.